Key takeaways
- A large fact table is a gold fact with a written grain.
- Key matching and enrichment are shared with sibling fact tables.
- (or a documented exception) for high-volume fact tables.
- Captions, folders, and descriptions required at publish.
- Bronze watermark and clean-view behavior documented beside the fact.
- Cross-fact join tests on fixture keys, including unmatched cases.
A source table named after the pipeline that fills it invites people to treat it like a disposable log. Reports then reinvent grain, matching, and captions in DAX. Volume pushes Import mode until refresh becomes the weekly outage.
Name the business concept. Enrich with the same matching logic used by the sibling fact table. Land it in gold for Direct Lake. Captions, query folders, and descriptions are part of the semantic handoff. Watermark shortcuts and clean views are part of the bronze-to-gold story, not footnotes.
Named model: large fact tables in gold
- Name: call the gold object what analysts say, not the pipeline's source table.
- Enrich: resolve keys against the dim table with the same matching module the sibling fact table uses.
- Store: Direct Lake is the default for high-volume fact tables when Delta layout cooperates; Import only as a bounded exception.
- Hand off: captions, query folders, descriptions, watermark docs, and fixture join tests ship with the fact.
- Contract: volume without grain and shared enrichment is just a faster mess. Mode choice does not forgive semantic drift.
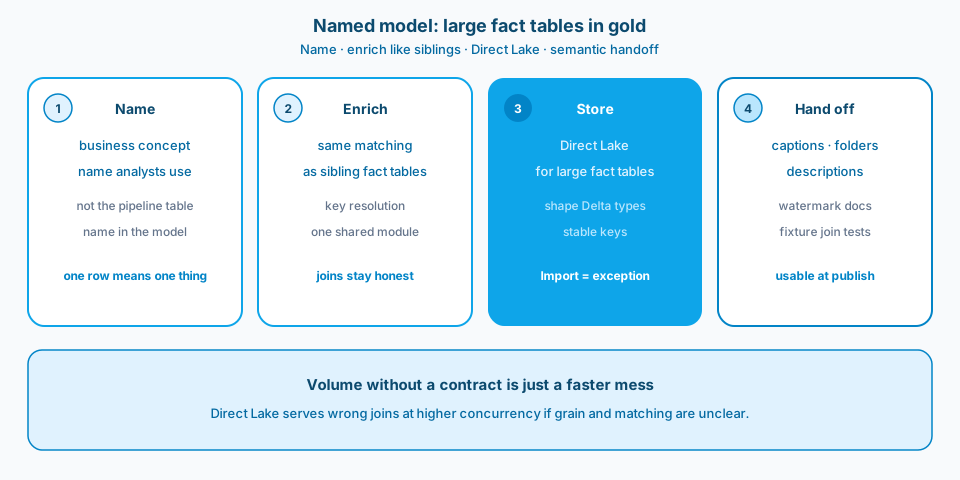
Figure 1. Large fact tables in gold. Name the business concept, enrich like the sibling fact table, prefer Direct Lake for volume, and hand off captions with the table.
Context and constraint
A common failure: row volumes that were "fine in the lab" meet Import refresh windows and mismatched keys versus a sibling fact table. The lake had data. The had a log with aspirations.
Direct Lake is the default posture for large fact tables when Delta layout cooperates. Import is a trap at this grain. Enrichment must align with the sibling fact table's matching so reports join cleanly instead of arguing across pages. Bronze watermarks and clean views feed gold; they do not replace a fact contract.
Figure 2 is the Learn surface that makes the destination story visible: high-volume data lands as modeled destinations, not as a log pile that only Import can fake into a report.
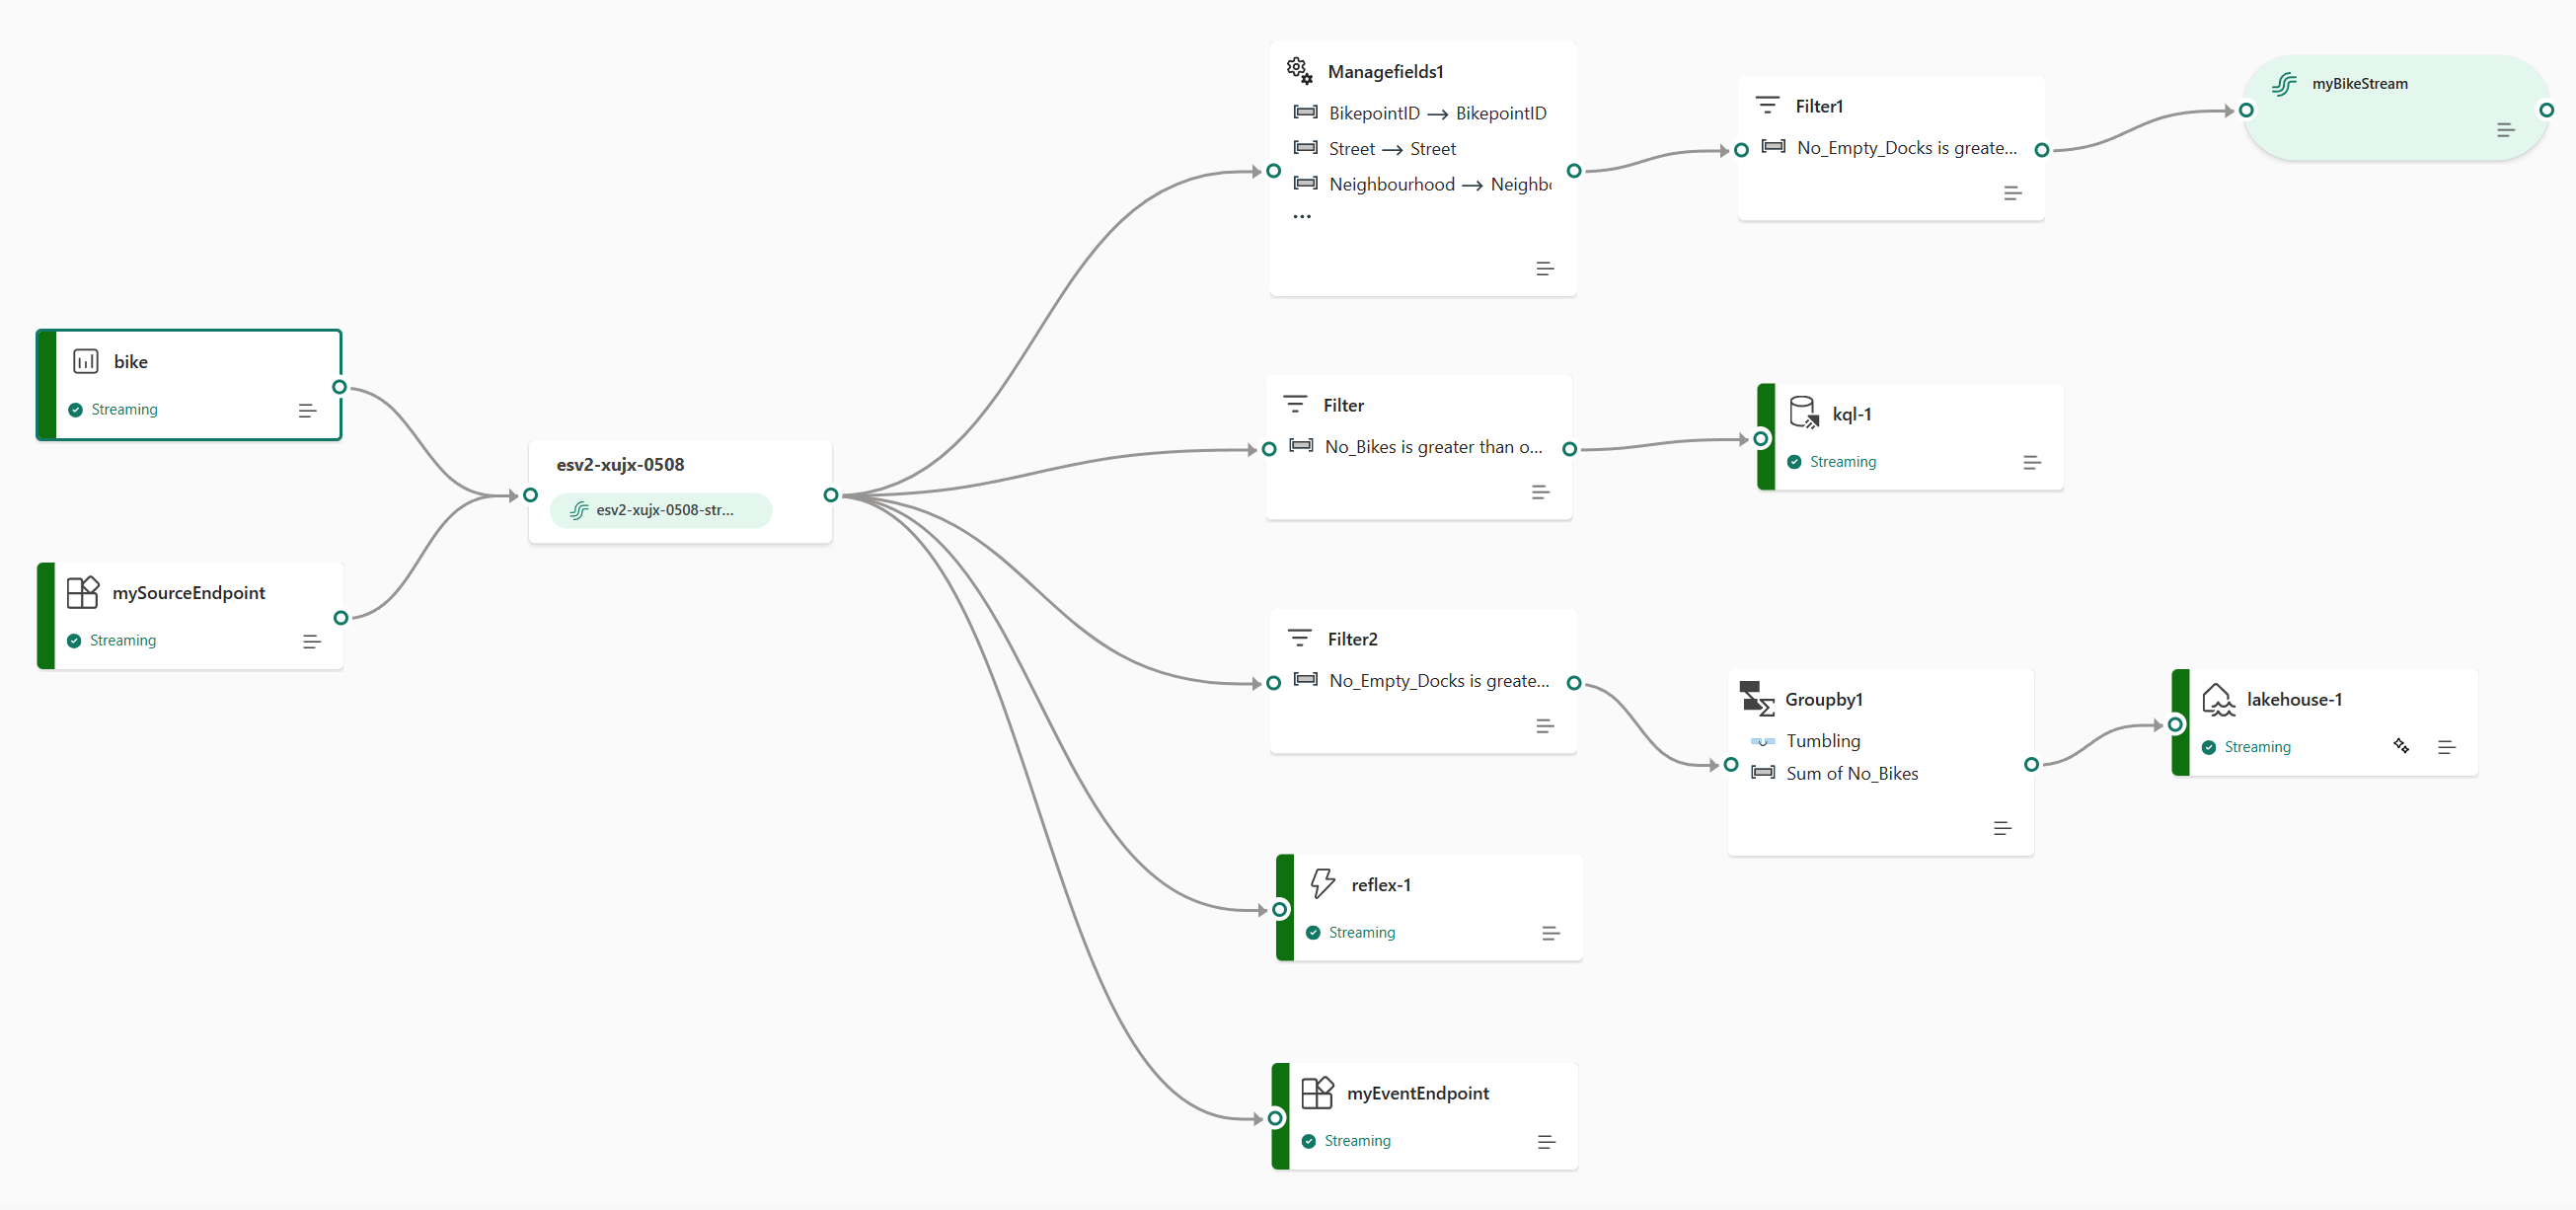
Figure 2. High-volume data is a fact. Land it as a modeled destination, not as a log pile that only Import mode can fake into a report. Source: Microsoft Learn: Eventstreams overview.
Design
1. Name the business concept, not the pipeline table
Call the gold object what analysts say. Pipeline names (source_table_v3_compact) belong in lineage docs, not in the semantic field list. Language shapes whether people model a fact or a dump.
2. Share matching logic with the sibling fact table
If fact table A resolves keys against a dim table with a module, fact table B uses the same module. Divergent matching produces counts that disagree across pages. Shared logic is a platform rule, not a courtesy. Figure 3 is that ownership split.
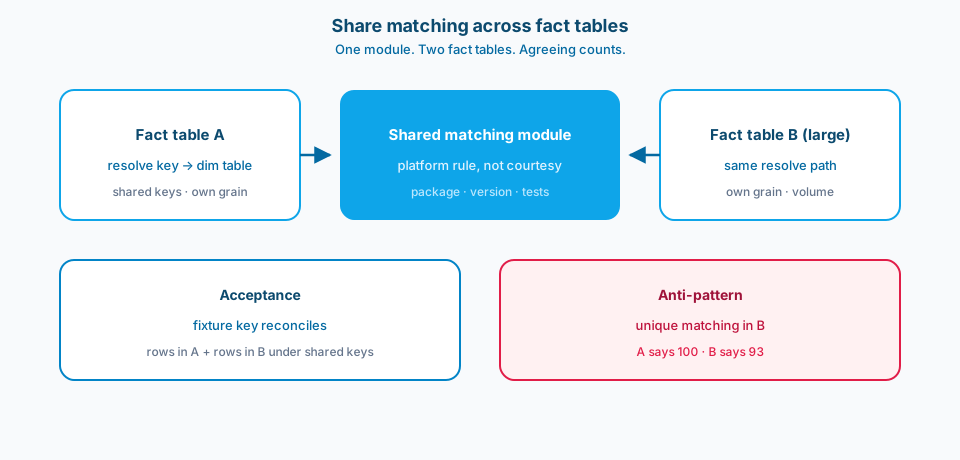
Figure 3. Share matching across fact tables. One module keeps shared keys aligned. Unique matching in B is how A says 100 and B says 93.
3. Prefer Direct Lake for volume
Wide history and high ingest rates punish Import refresh and capacity. Shape Delta for Direct Lake: sensible types, stable keys, avoid forcing SQL endpoint views in front when they reintroduce latency. Document when a hybrid Import dimension plus Direct Lake fact is intentional. Figure 4 is the default versus exception posture.
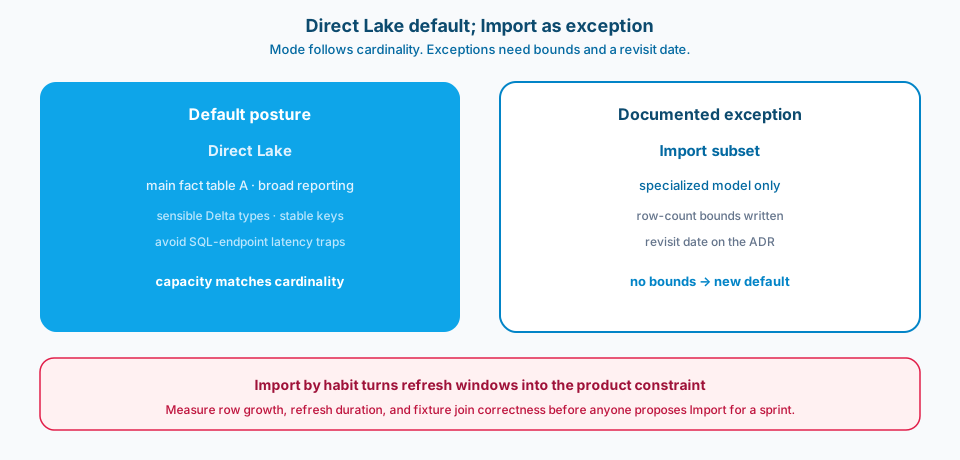
Figure 4. Direct Lake is the default for the main large fact table. Import is a documented exception with row-count bounds and a revisit date, not a habit.
4. Captions, folders, descriptions ship with the fact
Raw payload columns are cryptic. Human-facing captions and query folders are how the fact becomes usable. Include descriptions for units and enums. This is the same semantic handoff discipline as thinner gold tables, just more urgent at volume.
5. Bronze watermarks and cleans are part of the story
Shortcuts, watermark advances, and thin clean views explain freshness and late arrivals. Document them next to the gold fact contract so on-call knows whether a gap is ingest lag or a semantic filter. Do not leave watermark behavior as notebook tribal knowledge.
6. Test joins on known keys across facts
Acceptance includes: a key with rows in fact table A and rows in fact table B reconciles under the shared keys. Spot-check unmatched keys in B the same way you spot-check unmatched keys in A. Volume is not an excuse to skip grain tests; sample deliberately.
Import mode as a documented exception
Sometimes a small subset truly belongs in Import for a specialized model. Write that exception with row-count bounds and a revisit date. Exceptions without bounds become the new default. Direct Lake remains the posture for the main large fact table that feeds broad reporting. Clarity here prevents a future engineer from "simplifying" everything back to Import during an unrelated refactor.
Volume without a contract is just a faster mess
Direct Lake will not save a fact with unclear grain or divergent key matching. It will only help you serve the wrong joins at higher concurrency. Get the name, the shared enrichment, and the semantic handoff right first. Then choose Direct Lake so refresh and query capacity match the cardinality you already decided to trust.
Measure early: row growth per day, refresh duration under the chosen mode, and join correctness on a fixture pack. Numbers beat opinions when someone proposes falling back to Import "just for this sprint."
Capacity planning for Direct Lake still needs owners; mode choice without monitoring is just optimism.
Failure modes
Log mindset. No grain statement; every report invents one.
Import by habit. Refresh windows become the product constraint.
Unique matching. Fact table A says 100 keys; fact table B says 93.
Technical names in the model. Adoption dies; DAX forks multiply.
Undocumented watermarks. Freshness debates never end.
Skipping unmatched-key review. Silent drop of orphan rows.
What to copy / what not to copy
Copy
- A large fact table is a gold fact with a written grain.
- Key matching and enrichment shared with sibling fact tables.
- Direct Lake (or documented exception) for high-volume fact tables.
- Captions, folders, and descriptions required at publish.
- Bronze watermark and clean-view behavior documented beside the fact.
- Cross-fact join tests on fixture keys including unmatched cases.
Do not copy blindly
Direct Lake needs Delta hygiene and framing awareness. Import feels familiar and fails at scale. Shared enrichment modules require package discipline across notebooks. Caption work on wide fact tables takes time; skipping it costs every consumer hour. Keeping bronze watermark docs current is operational overhead that prevents false incident escalations.
Primary references: Direct Lake overview, guidance, and Power BI modeling docs for large facts. Pair storage mode choice with the enrichment contract so volume does not excuse semantic drift.
Name them, enrich them like their siblings, put them on Direct Lake, and hand off captions with the table. Volume then becomes a capacity story you can plan, not a weekly surprise refresh fire.