
Key takeaways
- Analytics reads a flat gold fact; nested source shapes stay out of Import pivots.
- PySpark performs a single documented pivot with broadcast attribute maps.
- Grain is one row per entity, attribute and period with stable keys; captions follow the business glossary.
- Delta output is ready; Import is not required for table width.
- Version the attribute map with the fact and document historical behavior.
- Parity checks gate cutover from OUTER APPLY Import paths.
Wide pivots arrive late. SQL OUTER APPLY, Import mode, captions invented in the report. Refresh time climbs. Direct Lake never gets a fair chance. The pays for a shape that should have been decided in gold.
Pivot once in gold. Broadcast joins plus a single groupBy/pivot in PySpark produce a self-contained fact with stable keys. Captions match the glossary users already know. Materialize for Direct Lake. Stop paying Import tax for wide pivots that only exist because the warehouse view stayed nested.
Named model: pivot once in gold
- Nested source: attribute bags and tree-shaped records. OUTER APPLY Import pivots and report-invented captions are the late tax.
- Gold Spark pivot: broadcast small attribute maps, then one groupBy/pivot. One job, one output grain, glossary captions.
- Flat Direct Lake fact: typed Delta the semantic model can consume without Import crutches. Versioned attribute map. Parity gates cutover.
- Contract: report-shaped pivots belong in gold materialization, not on the Import refresh path.
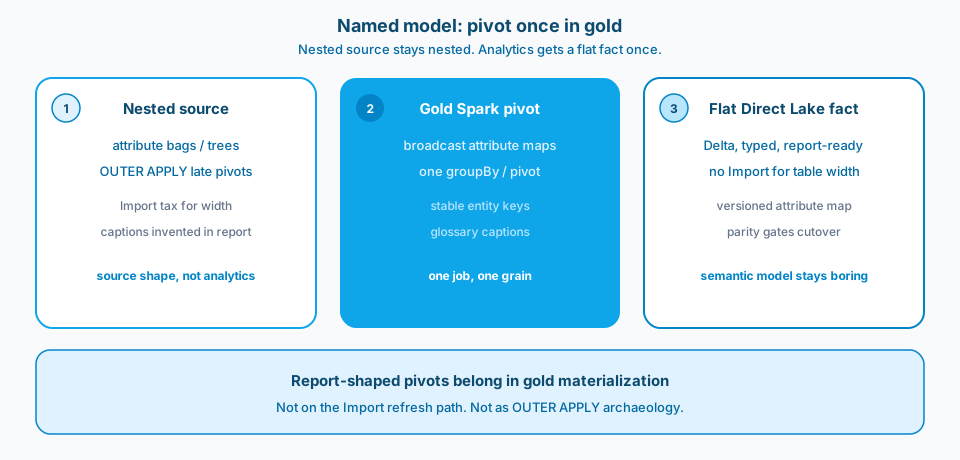
Figure 1. Pivot once in gold. Nested source stays operational. Analytics gets a flat, captioned fact the semantic model can explain without SQL archaeology.
Context and constraint
A common failure: source records arrive as nested attribute bags. Report authors pivot in SQL for Import. Every new attribute means another OUTER APPLY branch and a longer refresh. Moving the pivot into a gold Spark job makes the semantic model boring in the best way.
Nested bags are an operational convenience for source systems. Analytics needs flat facts with stable keys and business captions. Doing the reshape in Spark once beats reshaping in SQL on every Import. Direct Lake then reads a table that already looks like the report.
Figure 2 is the Learn surface for model relationships. Shape and keys matter before storage mode debates. A nested structure forced through Import is still the wrong analytical shape.
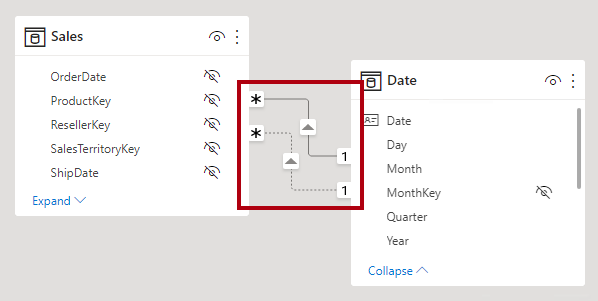
Figure 2. Relationship shape and keys are modeling decisions. Direct Lake wants report-ready flat facts, not nested trees that only Import mode can fake. Source: Microsoft Learn: understand relationships.
Design
1. Ban OUTER APPLY pivots on Import paths
If the only reason a model stays on Import is a wide pivot in SQL, move the pivot upstream. Import should be a storage-mode choice, not a tax for late shaping. Treat nested-to-wide SQL as a smell in code review.
2. Broadcast small dimensions, pivot once
Keep attribute definitions and caption maps small enough to broadcast. Drive a single groupBy/pivot over the source rows. One job, one output grain. Chained pivots and ad-hoc self-joins recreate the nested mess in Spark clothing.
3. One row per entity, attribute and period, with stable keys
Prefer a grain you can explain: entity key, attribute key, period, value, and status. Stable keys beat anonymous wide columns that drift when the source changes. Surrogate keys are fine; silent column renames are not. Figure 3 is that grain with caption discipline.
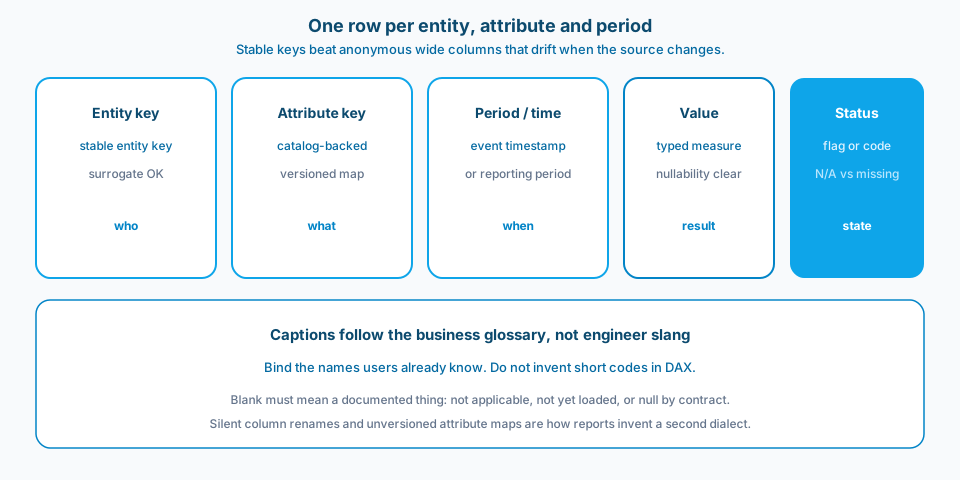
Figure 3. One row per entity, attribute and period with stable keys. Captions follow the glossary. Blank must mean a documented thing, not a private dialect.
4. Captions follow the business glossary, not engineer slang
Users already have names for attributes. Put those captions on the fact or a related dimension the semantic model can bind. Do not invent short codes in DAX that nobody uses. Language continuity is part of trust.
5. Materialize for Direct Lake deliberately
Write Delta with types and nullability that Direct Lake and the semantic model can consume without Import crutches. Validate column counts and key uniqueness in the notebook. A pivot that only works after a desktop Import is not done.
6. Version the attribute map with the fact
When attributes are added or retired, version the caption map and document how historical rows behave. Silent widening of the pivot without a contract is how yesterday's report breaks tomorrow's dashboard. Treat the attribute catalog as product data.
What the gold contract should say
Publish the grain, the key columns, the value columns, and the caption source. State whether missing attributes are null columns, absent rows, or a status flag. State how late corrections land. Semantic authors should not reverse-engineer the notebook to learn whether a blank means "not applicable" or "not yet loaded." Ambiguity in a flat fact becomes wrong numbers in meetings.
Direct Lake is not a free lunch without shape
Direct Lake rewards tables that are already analytical. Nested structs, exploding arrays in the model, and measure-time pivots push you back toward Import or toward painful DAX. If your story needs a pivot to be human-readable, do that pivot before the semantic model. Capacity metrics will look better, but the deeper win is a model reviewers can explain without a SQL archaeology session.
How to migrate without a big-bang cutover
Keep the old Import path readable while the gold fact proves parity. Compare row counts at the fact grain, spot-check a fixed set of attributes against the old output, and only then point the semantic model at the flat fact. Deprecate the OUTER APPLY view with a date. Dual-running without a kill date is how both paths rot. Figure 4 is that cutover order.
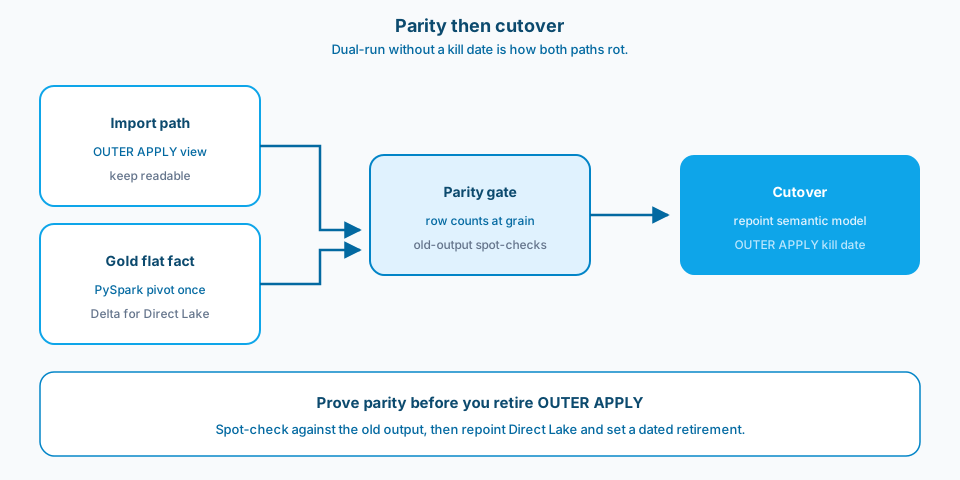
Figure 4. Prove parity before you retire OUTER APPLY. Spot-check against the old output, then repoint Direct Lake and set a dated retirement.
Failure modes
Nested forever. Source shape becomes analytics shape by inertia.
Import as apology. Wide SQL pivots force Import; nobody asks why.
Caption drift. Engineers rename columns; business users stop recognizing measures.
Multi-step Spark pivots. Intermediate wide tables nobody owns.
No grain ADR. Two authors disagree on "one row per what" mid-incident.
Glossary ignored. Report labels invent a second dialect.
What to copy / what not to copy
Copy
- Analytics reads a flat gold fact; nested source shapes stay out of Import pivots.
- PySpark performs a single documented pivot with broadcast attribute maps.
- Grain is one row per entity, attribute and period with stable keys; captions follow the business glossary.
- Delta output is Direct Lake ready; Import is not required for table width.
- Attribute map changes are versioned with explicit historical behavior.
- Parity checks gate cutover from OUTER APPLY Import paths.
Do not copy blindly
Pre-pivoting in gold adds a Spark job and an attribute-map dependency. Late SQL pivots feel flexible until refresh and Direct Lake are on the table. Wide facts can be column-heavy; that is still cheaper than Import theatre when the grain is honest. Caption discipline slows the first delivery and speeds every review after. Versioning the attribute map is ceremony; unversioned maps are incidents.
Primary references: Direct Lake overview and Fabric Spark/Delta guidance on Microsoft Learn. Pair them with an ownership doc for the attribute catalog so captions have a human owner. Relationship modeling context: understand relationships.
Flatten in gold. Caption in the business language. Materialize for Direct Lake. Leave OUTER APPLY pivots in the history folder where they belong.